Back to all posts
local llm vram requirements
Found 4 articles tagged with "local llm vram requirements"
Guide
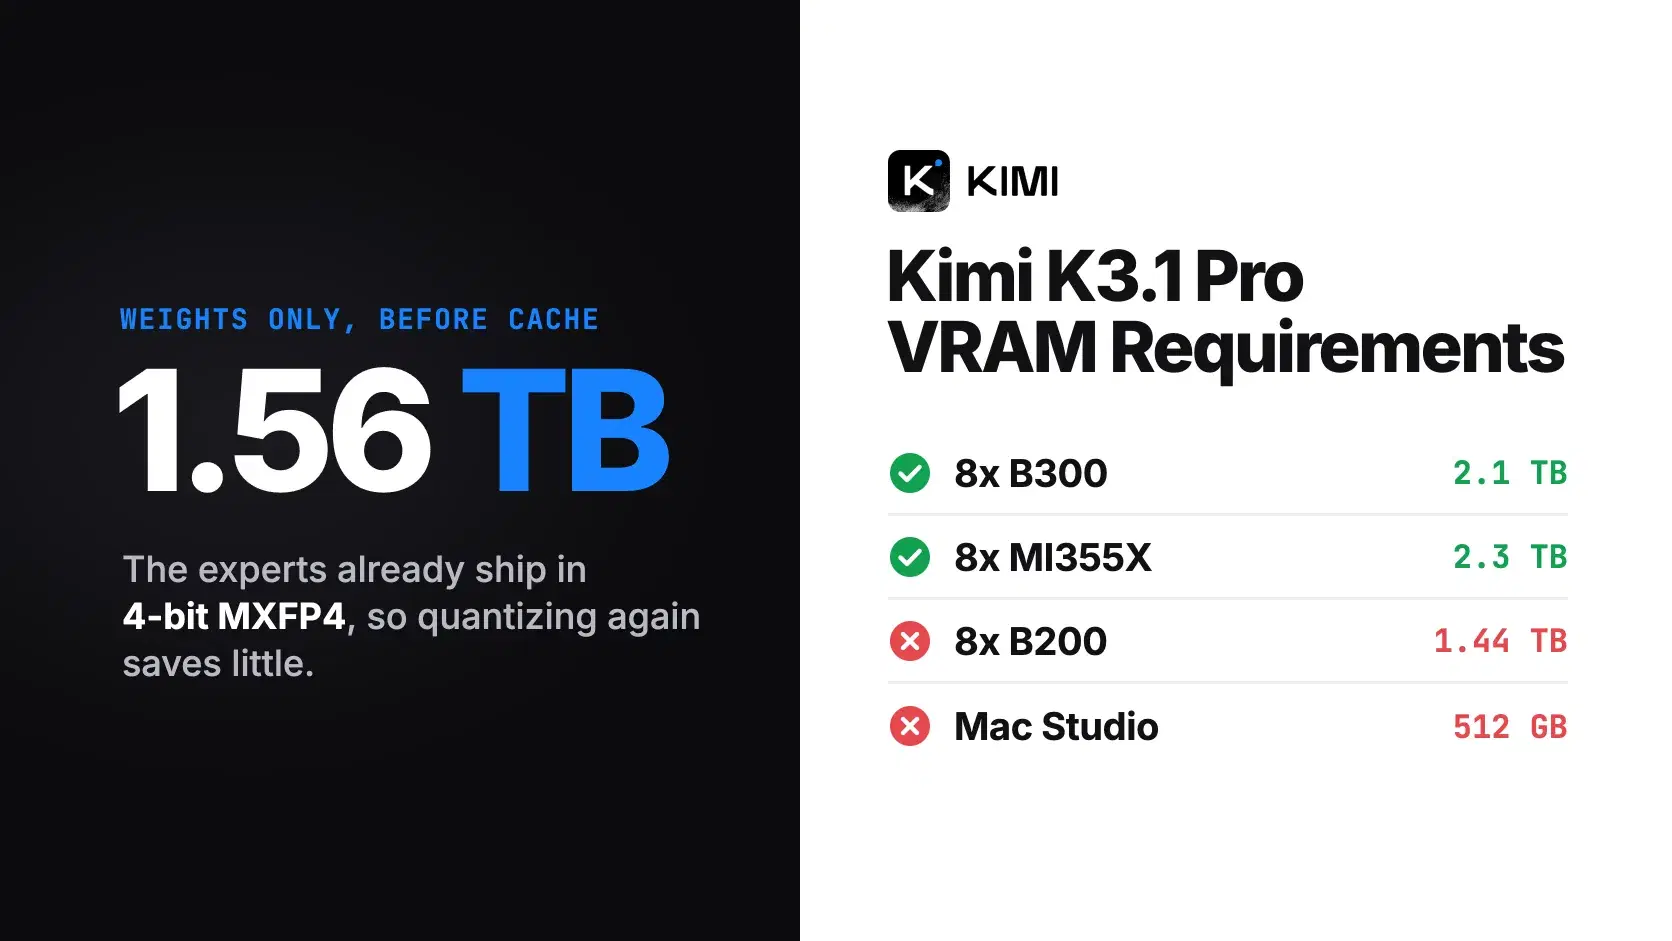
8 min readKimi K3.1 Pro VRAM Requirements

Latest Articles
Guide
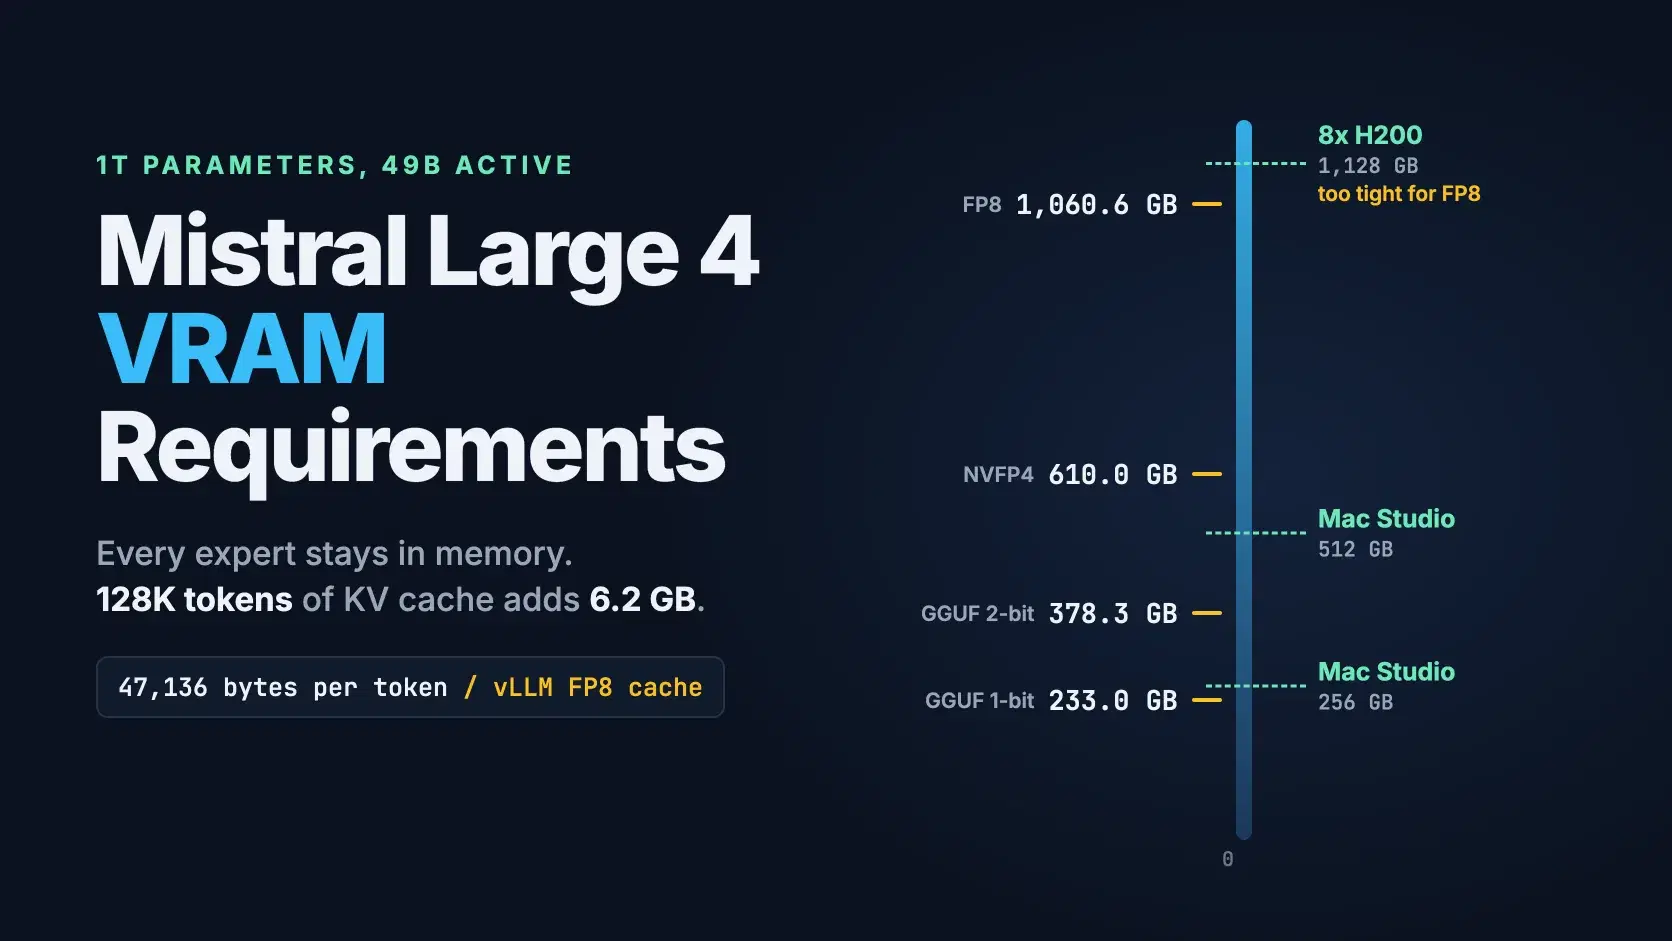
9 minMistral Large 4 VRAM Requirements
Mistral Large 4 needs 1.06 TB in FP8, 610 GB in NVFP4 and 233 GB at 1-bit. Which GPU nodes and Macs fit it, and what 128K of KV cache adds.
DevToolLab Team·
Guide
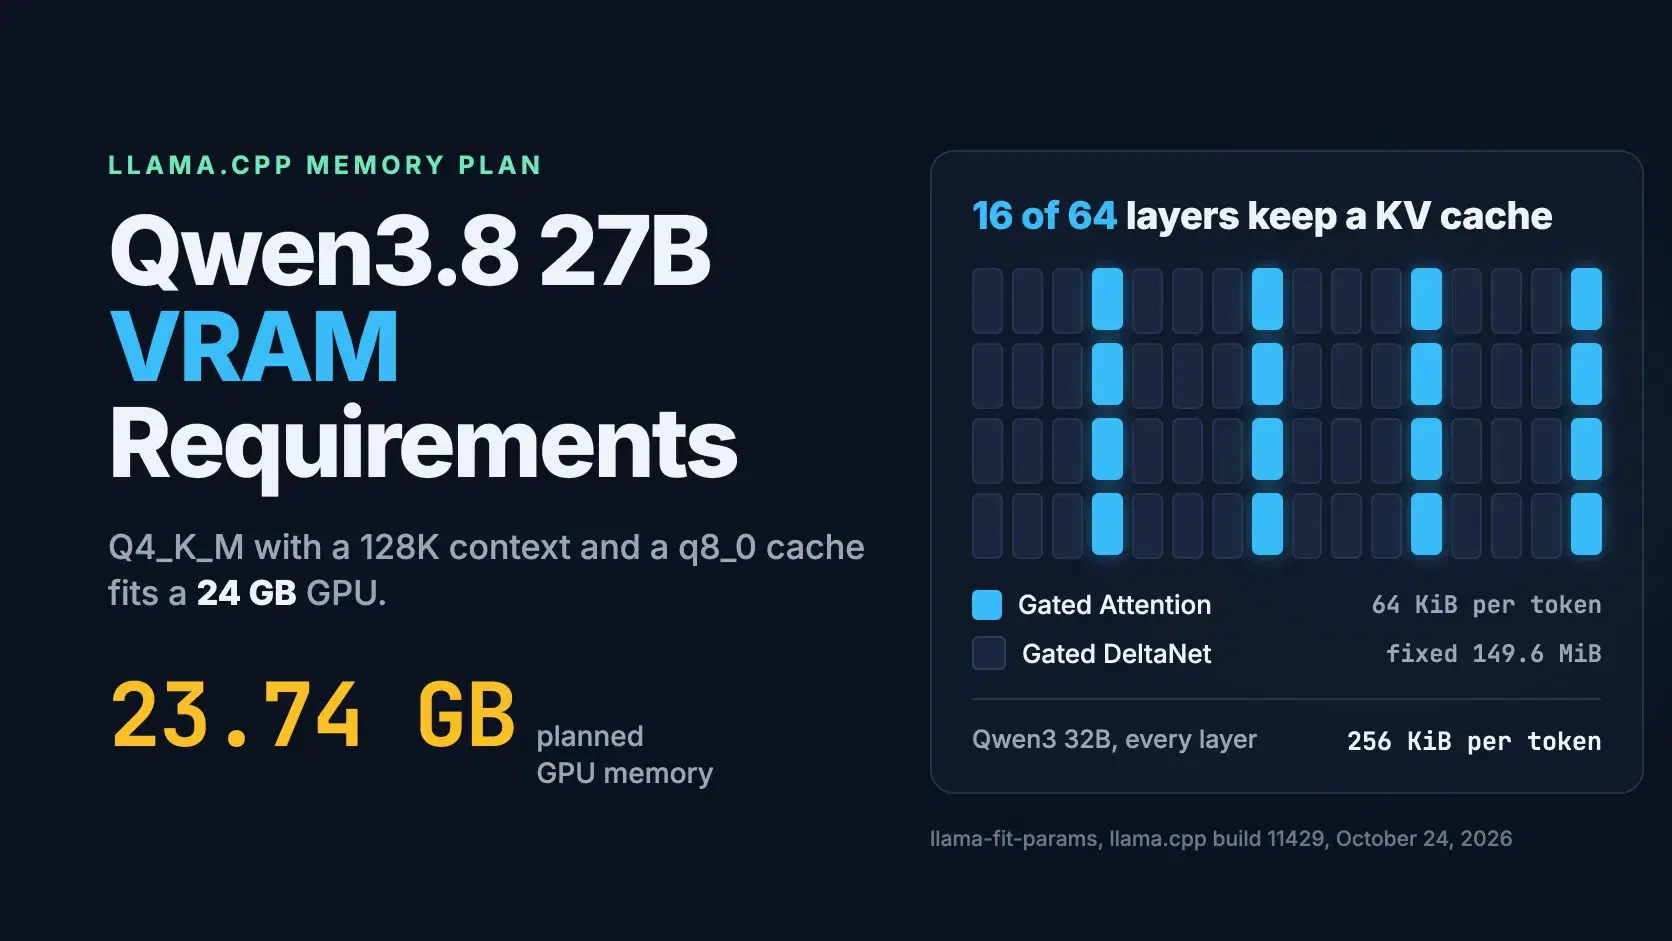
9 minQwen3.8 27B VRAM Requirements, Measured
Qwen3.8 27B at Q4_K_M needs 23.74 GB of GPU memory for 128K tokens with a q8_0 cache. llama.cpp's own plan for 16, 24 and 32 GB GPUs.
DevToolLab Team·
Guide
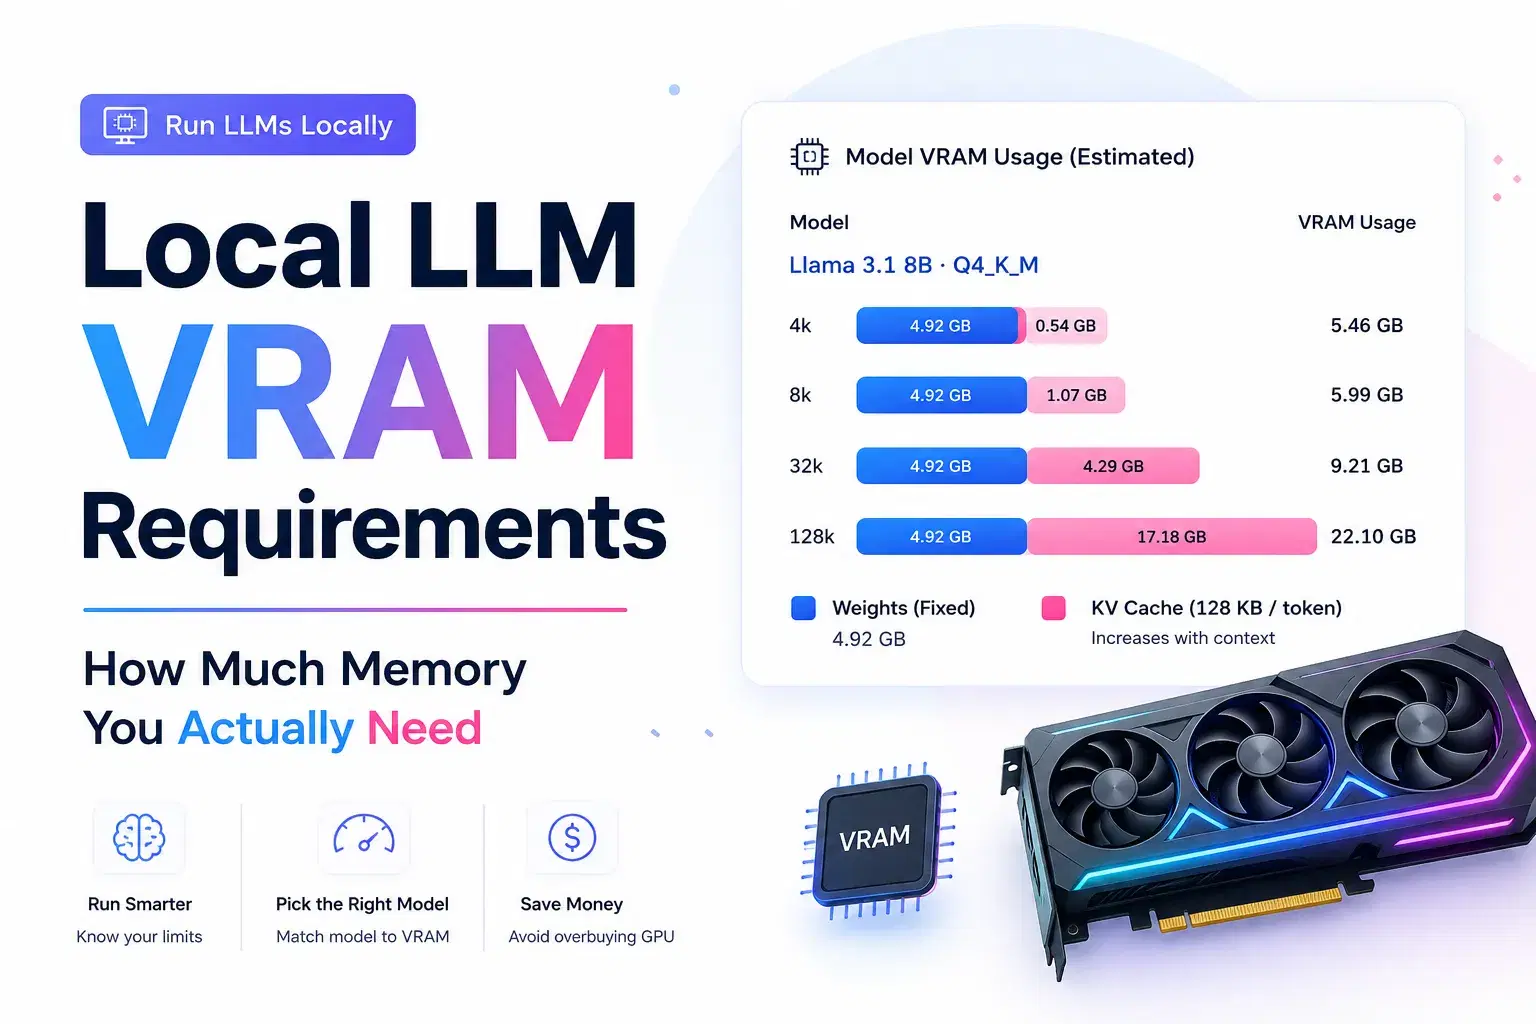
7 minLocal LLM VRAM Requirements: How Much Memory You Actually Need
A Q4_K_M 8B model is 23 percent bigger than the quant name implies, and at 128k context its KV cache is 3.5x the weights. The memory math for running local LLMs, checked against real GGUF file sizes.
DevToolLab Team·