Found 1 article tagged with "how much vram for llm"
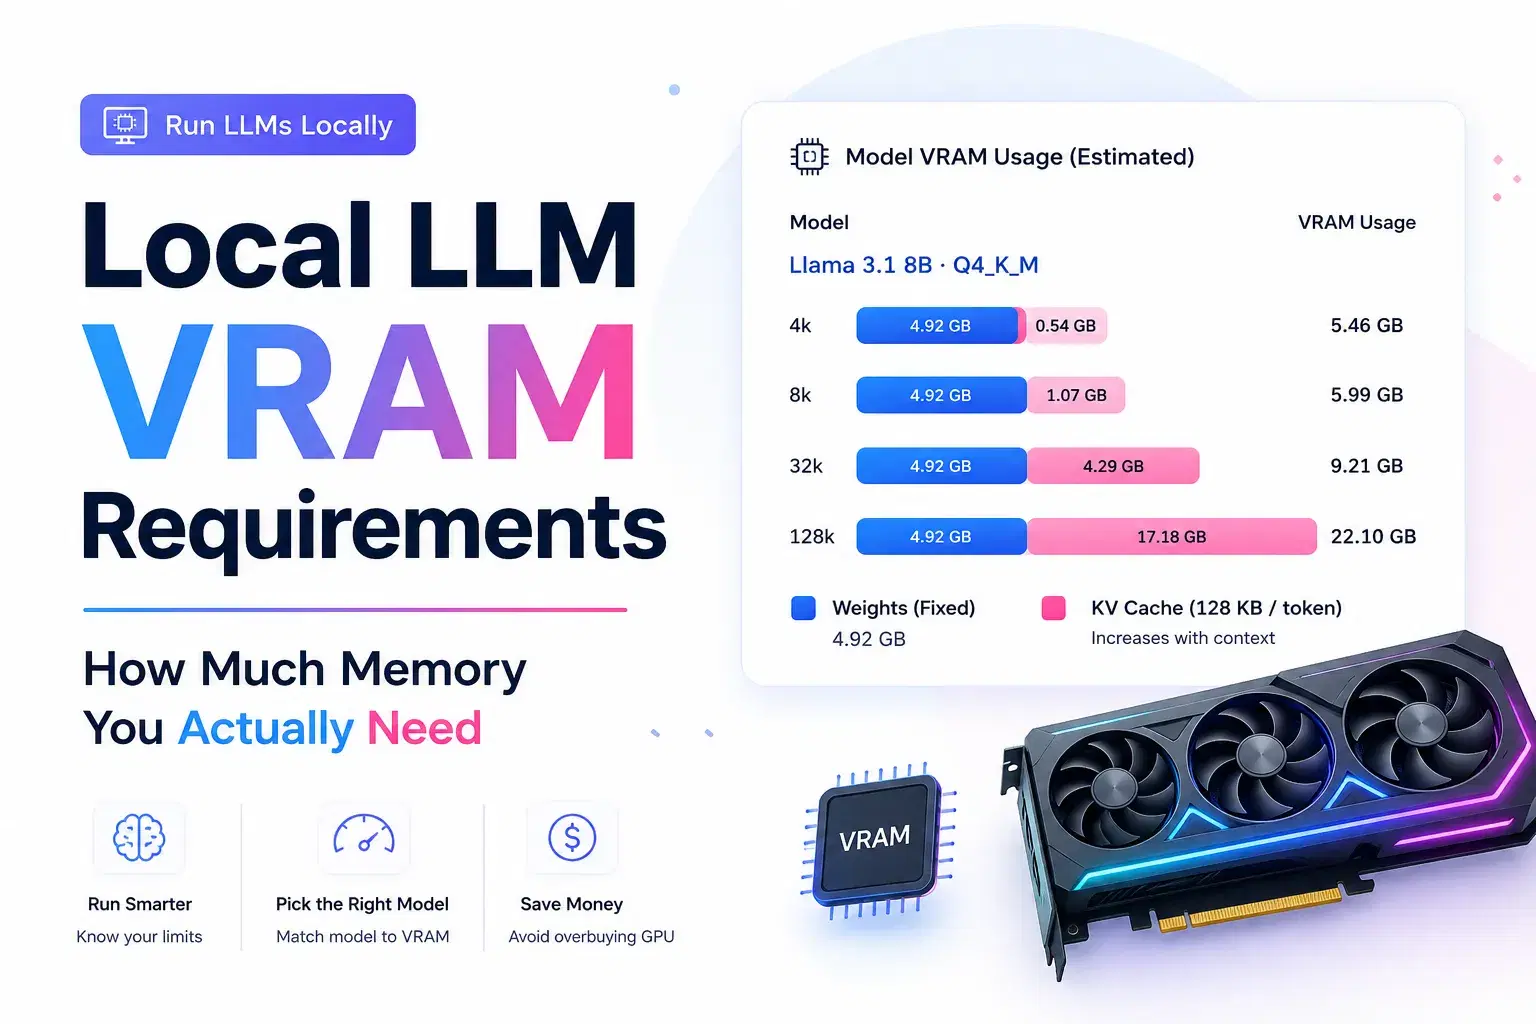
A Q4_K_M 8B model is 23 percent bigger than the quant name implies, and at 128k context its KV cache is 3.5x the weights. The memory math for running local LLMs, checked against real GGUF file sizes.