

An offline LLM is a language model whose weights sit on your own machine, so it keeps answering with the network unplugged. Running one has become an architectural choice: no token fees, no network latency, and no proprietary code leaving your machine.
The short answer for November 2026: MiMo-V2.6 (6.6 GB) or Gemma 4 12B on a laptop, Qwen3.8 27B or Gemma 4 26B on a 24 GB GPU, Flint if you want a local coding agent, and Ollama or LM Studio to run them.
The catch is that "open weights" and "runs on your hardware" are now two different things. Checked against Ollama's library on November 5 and 6, 2026, Qwen3.8 pulls as an 18 GB local file, while Kimi K3, GLM-5.3, MiniMax-M3 and DeepSeek-V4.1-Flash are listed only as cloud tags. The weights are public; the hardware to run them is not on your desk. This guide separates the two.
Why Migrate to Local LLMs in 2026?
- Privacy: prompts, schemas and API keys stay off third-party servers, which is often the simplest way to meet a data-residency rule for medical or financial code.
- Predictable unit economics: per-token pricing scales badly for pipelines doing millions of requests a day. Local inference is hardware upfront and zero variable spend.
- No network bottlenecks: no
429 Too Many Requests, no TLS overhead, no vendor outage taking your feature down. - Full parameter control: open weights let you change sampling and fine-tune on proprietary data without uploading it anywhere.
At a Glance: Top Local LLM Hardware & Software
Top 5 Local Inference Frameworks
| Tool | Primary Use Case | Current version, checked November 5, 2026 |
|---|---|---|
| Ollama | Seamless CLI & Background Daemons | v0.40.14 (November 3), MIT, 185,964 GitHub stars |
| LM Studio | Visual Model Management | 0.4.28 (October 31), closed-source app |
| Text Gen WebUI (now "TextGen") | Advanced Research & Tweaking | v4.9 (May 20), AGPL-3.0, 47,734 stars, desktop app |
| LocalAI | Dropping Cloud Dependencies | v4.12.1 (October 23), MIT, 50,210 stars |
| Jan | 100% Offline Desktop Chat | v0.8.8 (October 28), 45,476 stars |
GPT4All, which held the fifth spot before Jan, has not had a commit since May 27, 2025 or a release since February 25, 2025. It still runs but is unmaintained.
Top Models for Local Inference (November 2026)
Verified against Ollama's library and Hugging Face on November 5 and 6, 2026. "Local tag" means there is a downloadable weight file, not just a hosted endpoint.
| Foundation Model | Developer | Ollama local tag | Download size | License |
|---|---|---|---|---|
| MiMo-V2.6 (9B) | Xiaomi MiMo | mimo-v2.6 | 6.6 GB | MIT |
| Gemma 4 (12B) | gemma4:12b | 7.7-8.0 GB | Apache 2.0 | |
| Gemma 4 (26B MoE) | gemma4:26b | 16-19 GB | Apache 2.0 | |
| Qwen3.8 (27B dense) | Alibaba | qwen3.8:27b | 18 GB | Apache 2.0 |
| Flint (40B MoE) | Recursive | flint | 22.9 GB | Apache 2.0 |
| DeepSeek-V4-Pro | DeepSeek | none (cloud only) | n/a | MIT |
| GLM-5.3 | Zhipu AI | none (cloud only) | n/a | glm-5.3 |
| MiniMax-M3 | MiniMax | none (cloud only) | n/a | minimax-community |
| Inkling | Thinking Machines Lab | community GGUF only | n/a | Apache 2.0 |
| Kimi K3 | Moonshot AI | none (cloud only) | n/a | kimi-k3 |
Five of the ten rows have a real local tag (Gemma 4 appears twice, so nine distinct models). The other five are open-weight in the licensing sense and data-center-scale in the practical sense.
Deep Dive: The Top 5 Local Inference Engines
1. Ollama (The Absolute Standard)
ollama launches an agent that helps you code and delegate work, per its release notes.
Bashcurl -fsSL https://ollama.com/install.sh | sh # tags and sizes as listed on ollama.com/library, November 6, 2026 ollama run mimo-v2.6 # 6.6 GB, laptop-friendly ollama run gemma4:12b # 7.7-8.0 GB, text and images ollama run qwen3.8:27b # 18 GB ollama run flint # 22.9 GB, coding agents
Ollama also serves an OpenAI-compatible endpoint, so existing client code only needs a new base URL:
Bashcurl http://localhost:11434/v1/chat/completions -d '{ "model": "gemma4:12b", "messages": [{"role": "user", "content": "Explain async/await in Python"}] }'
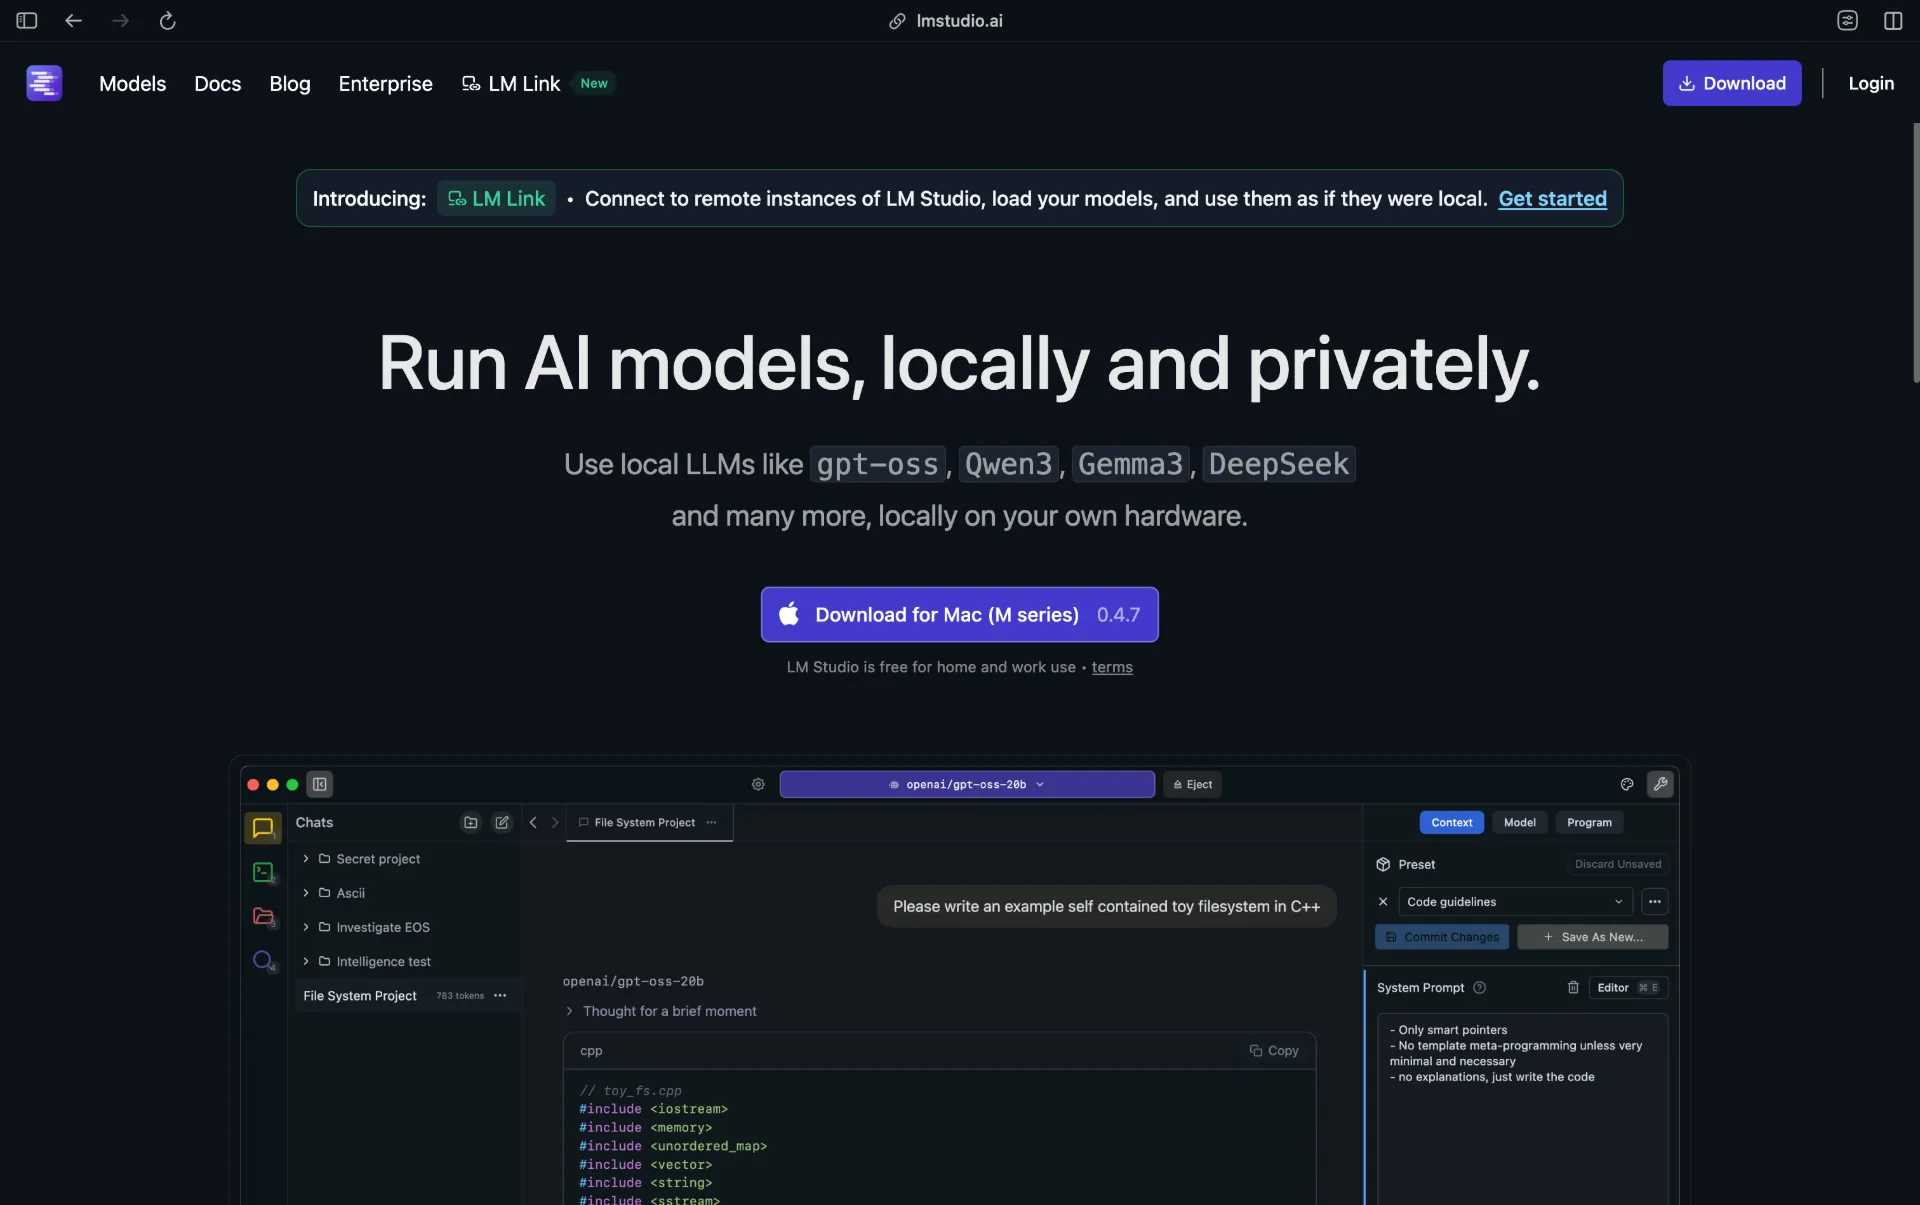
2. LM Studio (The Best GUI)
3. Text Generation WebUI, now TextGen (For the Power User)
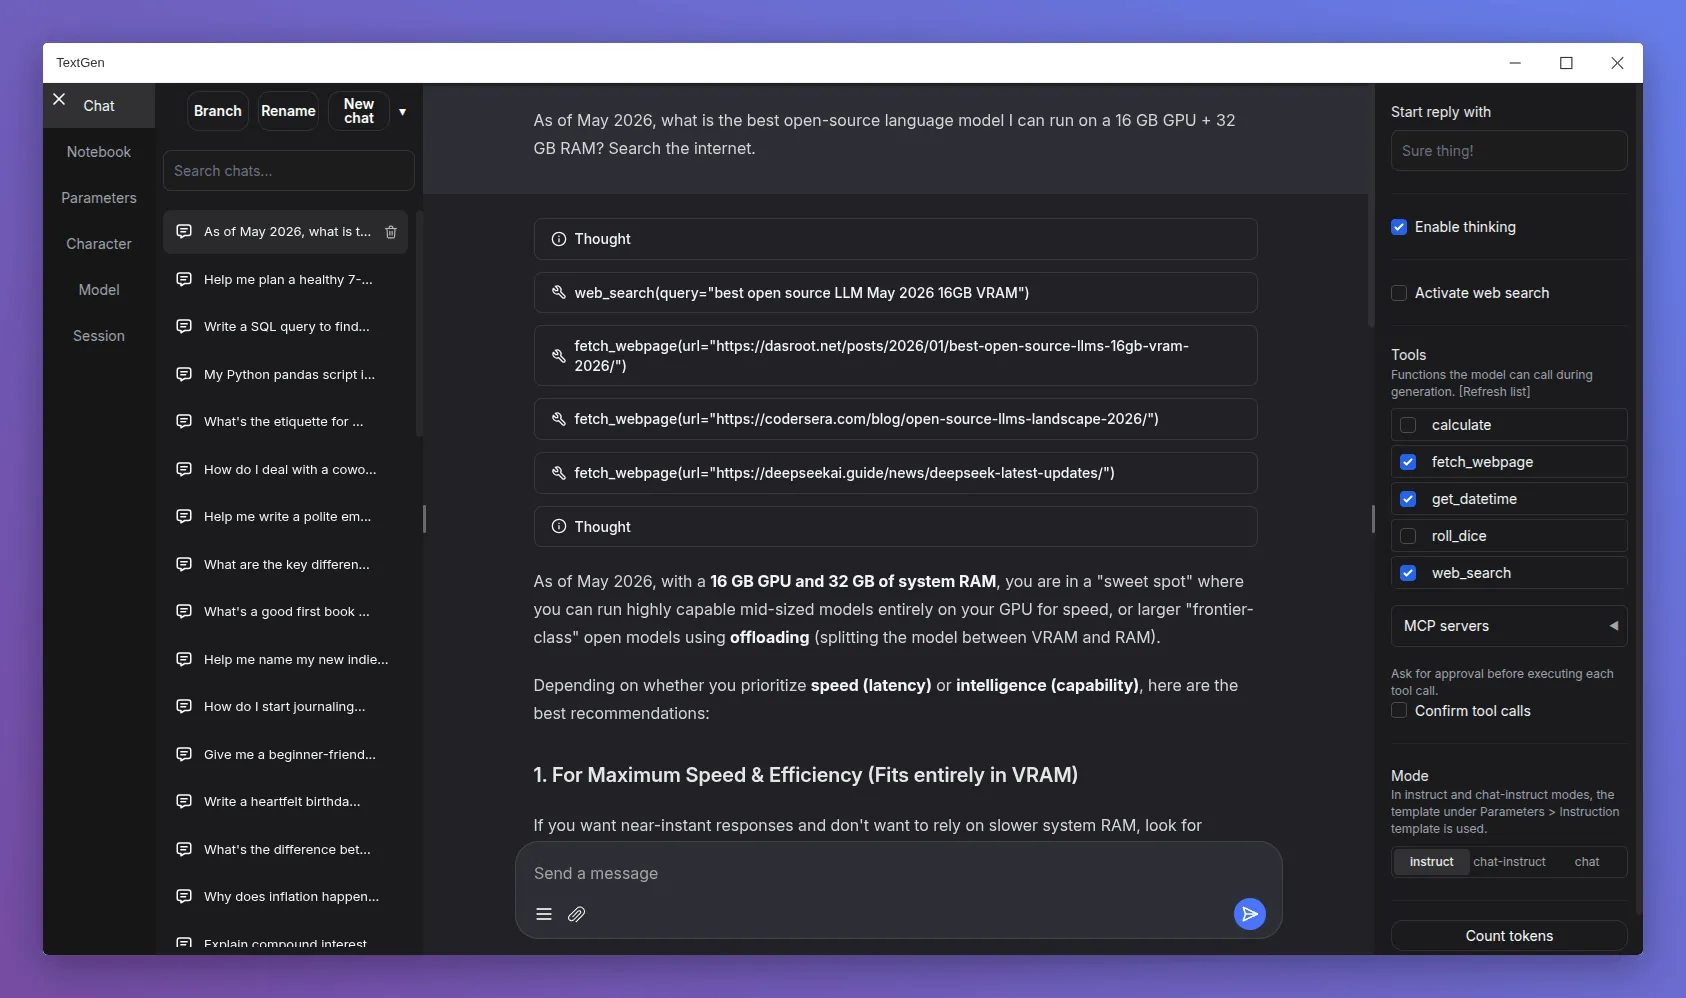
oobabooga/text-generation-webui, and its README now calls it "a desktop app for local LLMs", open source with no telemetry. The latest release is v4.9 (May 20, 2026); portable builds exist for Linux, Windows and macOS.
4. LocalAI (The Drop-In Replacement)
latest; the latest-cpu tag has not been updated since June 2025.
Bashdocker run -ti --name local-ai -p 8080:8080 localai/localai:latest docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-gpu-nvidia-cuda-12
Point your OpenAI base URL at http://localhost:8080 and existing code routes through your own GPU.
5. Jan (The Actively Maintained Desktop Casual)
Best Open Source LLMs for Local Running in 2026
MiMo-V2.6 (9B)
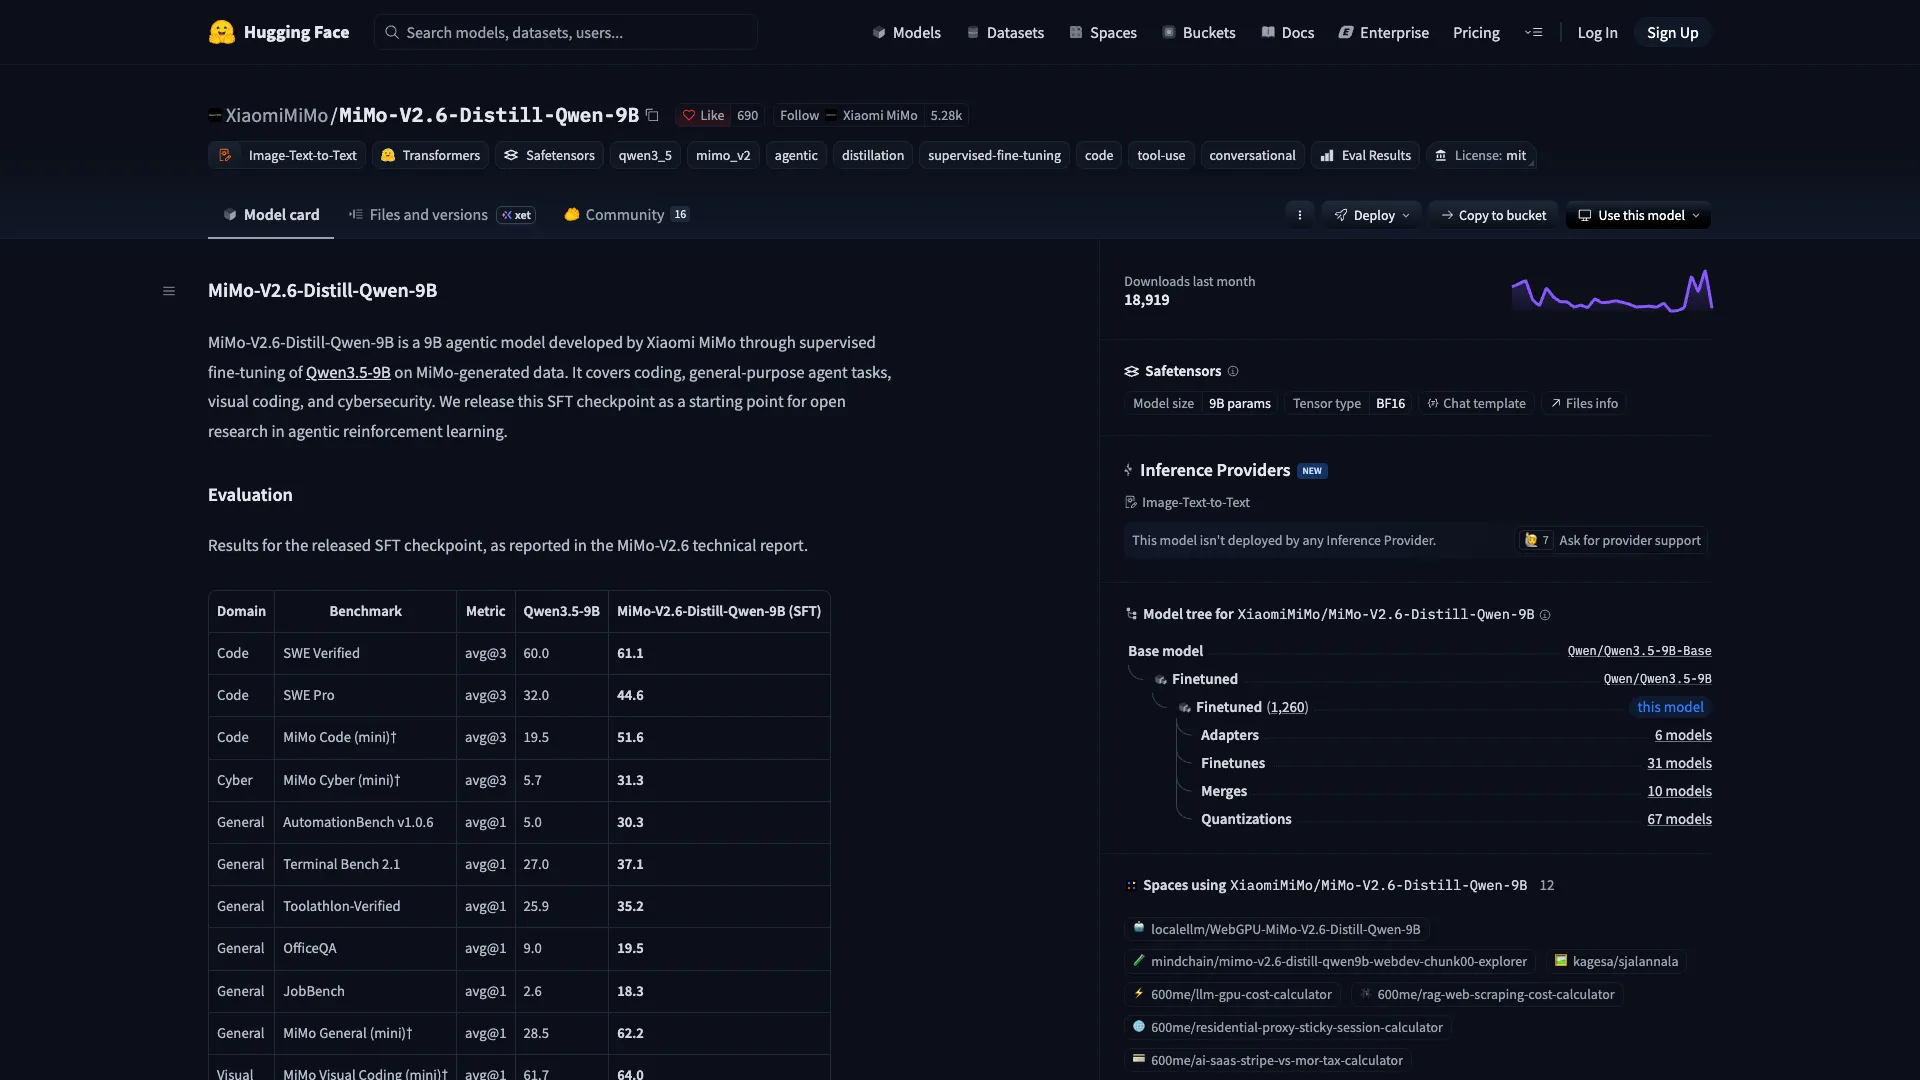
MiMo-V2.6-Distill-Qwen-9B is a 9B agentic model that Xiaomi built by fine-tuning Qwen3.5-9B on MiMo-generated data for coding, tool use and cybersecurity. It pulls as a 6.6 GB file on Ollama, so it fits an 8 GB card with a little room. On Xiaomi's own table it scores 61.1 on SWE Verified against 60.0 for the base model and 44.6 on SWE Pro against 32.0, though several of its other rows come from internal evaluation sets.
What it is not: a finished model. Xiaomi calls the checkpoint a starting point for agentic reinforcement learning research.
ollama run mimo-v2.6 # 6.6 GB
Gemma 4
Gemma 4 12B is the most accessible quality model here at 7.7-8.0 GB, with a 256K context window and text and image input per Ollama's listing, and 1,768,358 Hugging Face downloads in the last 30 days. The 26B MoE variant is listed at 16-19 GB on Ollama (the manifest for the default tag sums to 18.7 GB) and has 5,770,236 downloads. A 31B dense tag exists at 19-20 GB.
Bashollama run gemma4:12b # 7.7-8.0 GB ollama run gemma4:26b # 16-19 GB
Qwen3.8 (27B)
Qwen3.8-27B is the strongest model in this list that still fits on one consumer GPU: an 18 GB pull, dense rather than MoE, and the most downloaded model here at 8,032,442 Hugging Face downloads in the 30 days to November 5, 2026, ahead of Gemma 4 26B at 5,770,236.
ollama run qwen3.8:27b
Flint (40B MoE)
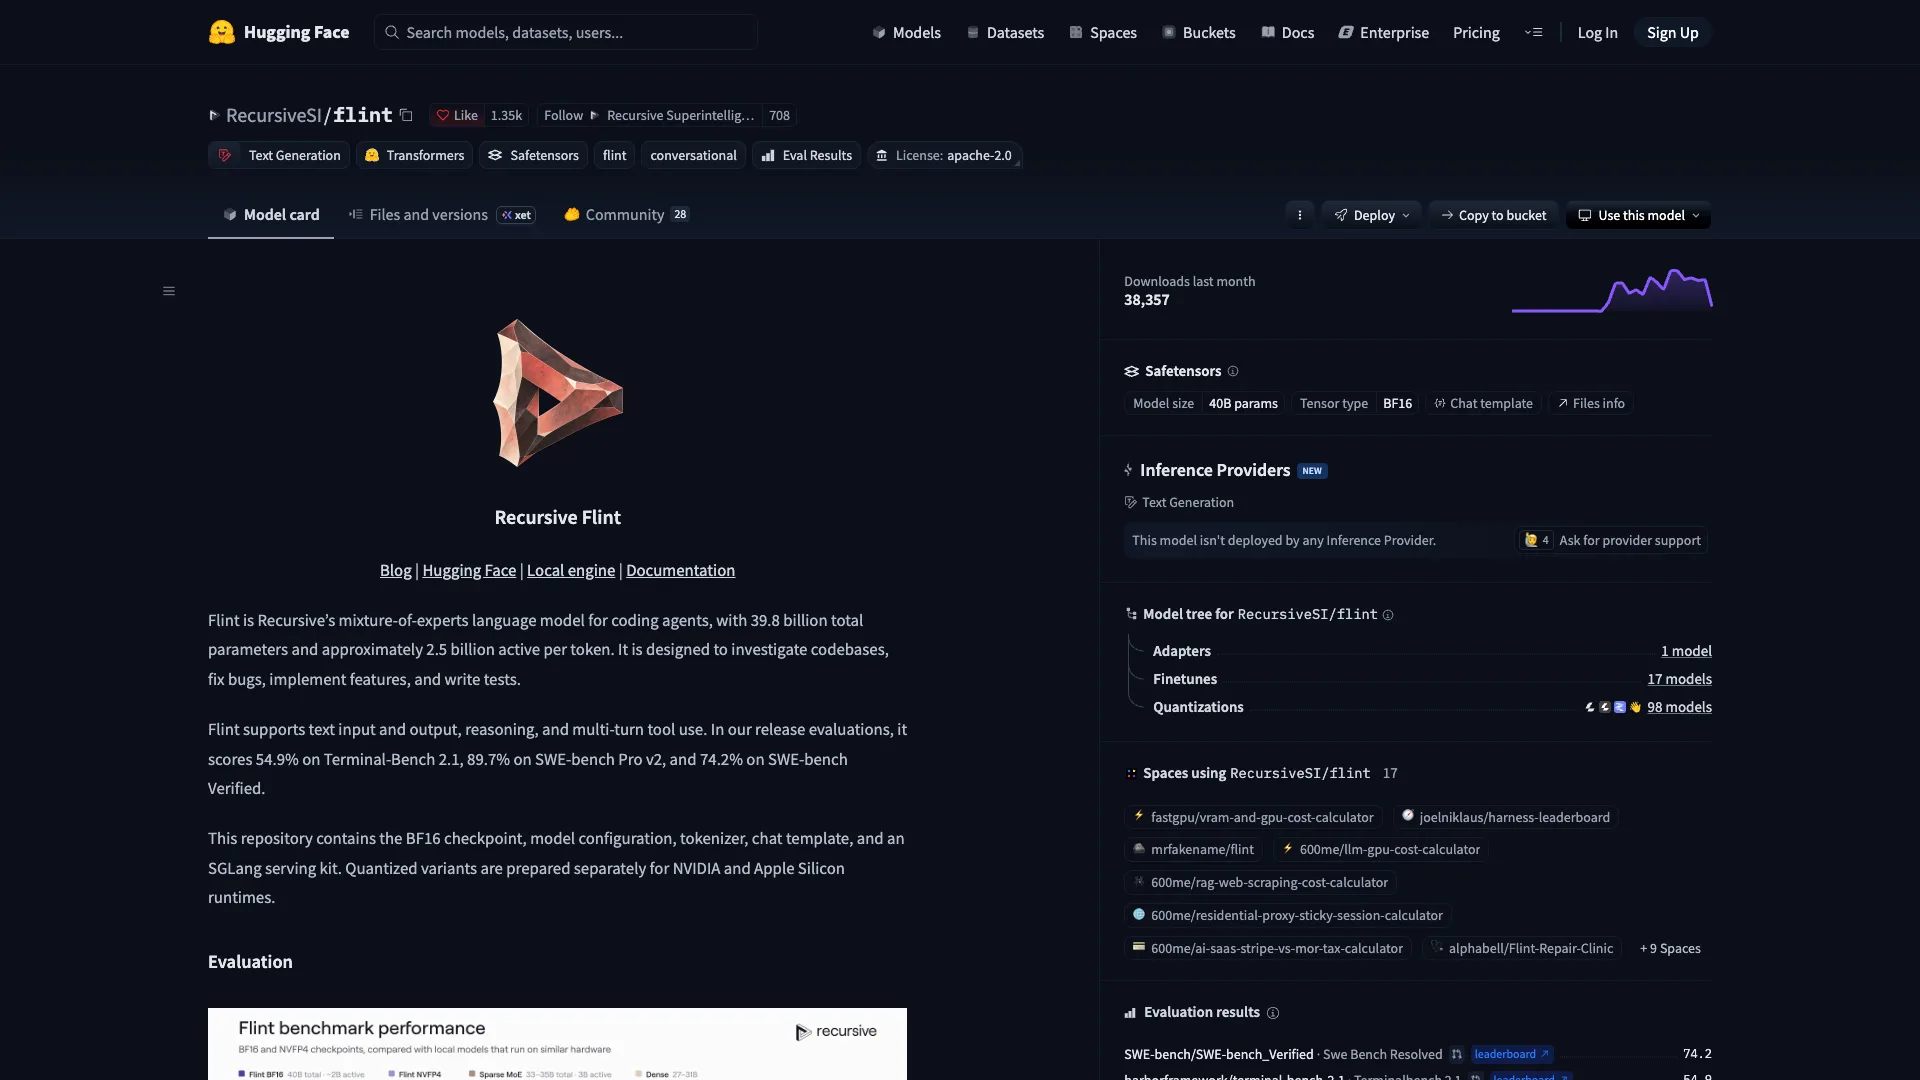
Flint is a mixture-of-experts model for coding agents with 39.8B total and about 2.5B active parameters per token and a 262K-token context, published in October 2026. Ollama's flint tag is a 22.9 GB pull and works with ollama launch claude --model flint, per its library page. Recursive reports 74.2% on SWE-bench Verified and 54.9% on Terminal-Bench 2.1; those are publisher numbers, and the Terminal-Bench figure counts web-retrieved solutions as failures.
What it is not: roomy on a 24 GB card. The weights alone take 22.9 GB, which leaves little for the KV cache at long context, so a 32 GB GPU or a Mac with more memory suits it better.
ollama run flint # 22.9 GB
DeepSeek-V4-Pro and DeepSeek-V4.1-Flash
DeepSeek AI, MIT licensed
DeepSeek-V4-Pro (336,935 Hugging Face downloads in 30 days) and the newer DeepSeek-V4.1-Flash (1,950,966) are open-weight, and both appear on Ollama as cloud tags only. Running either yourself means a private inference server, not a desk.
GLM-5.3
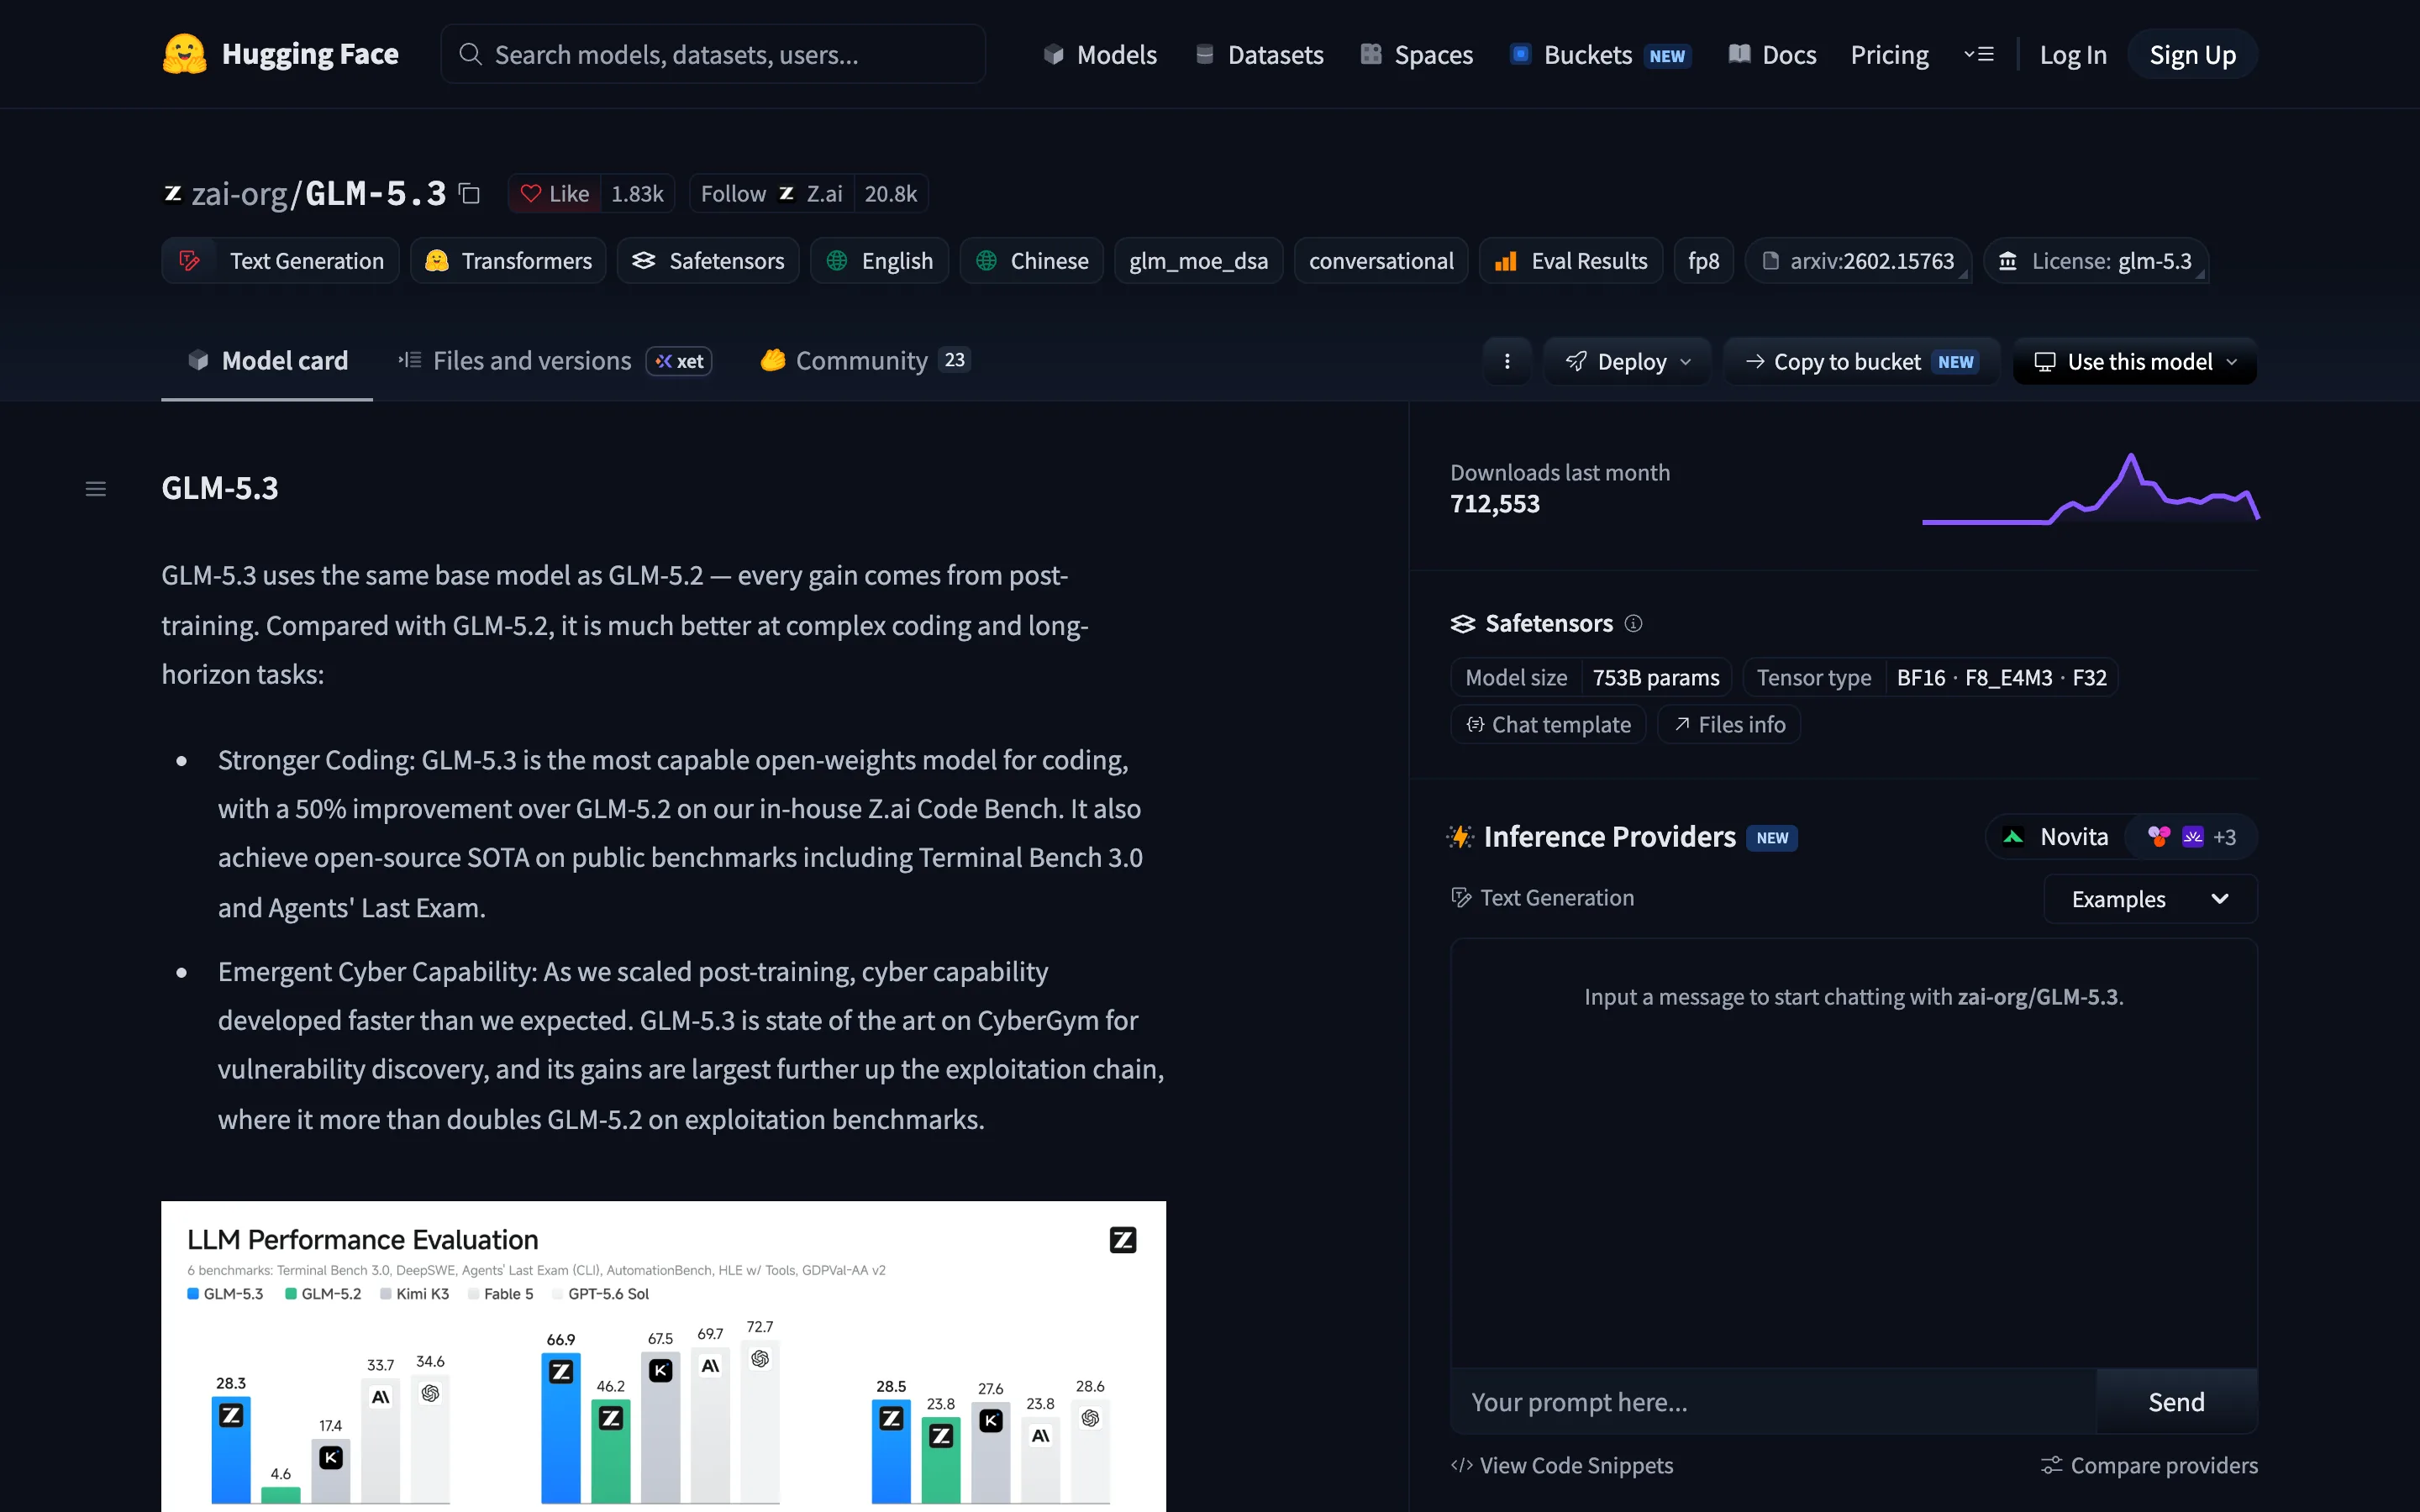
GLM-5.3 is a 753B-parameter model. Its model card says it uses the same base model as GLM-5.2 and that every gain comes from post-training, including a claimed 50 percent improvement on Z.ai's in-house code benchmark. It has 2,287,718 Hugging Face downloads in the 30 days to November 5, 2026, and is cloud-only on Ollama. GLM-5.3-Flash, a smaller sibling under the MIT license, has 6,303,033 downloads and is also cloud-only.
MiniMax-M3
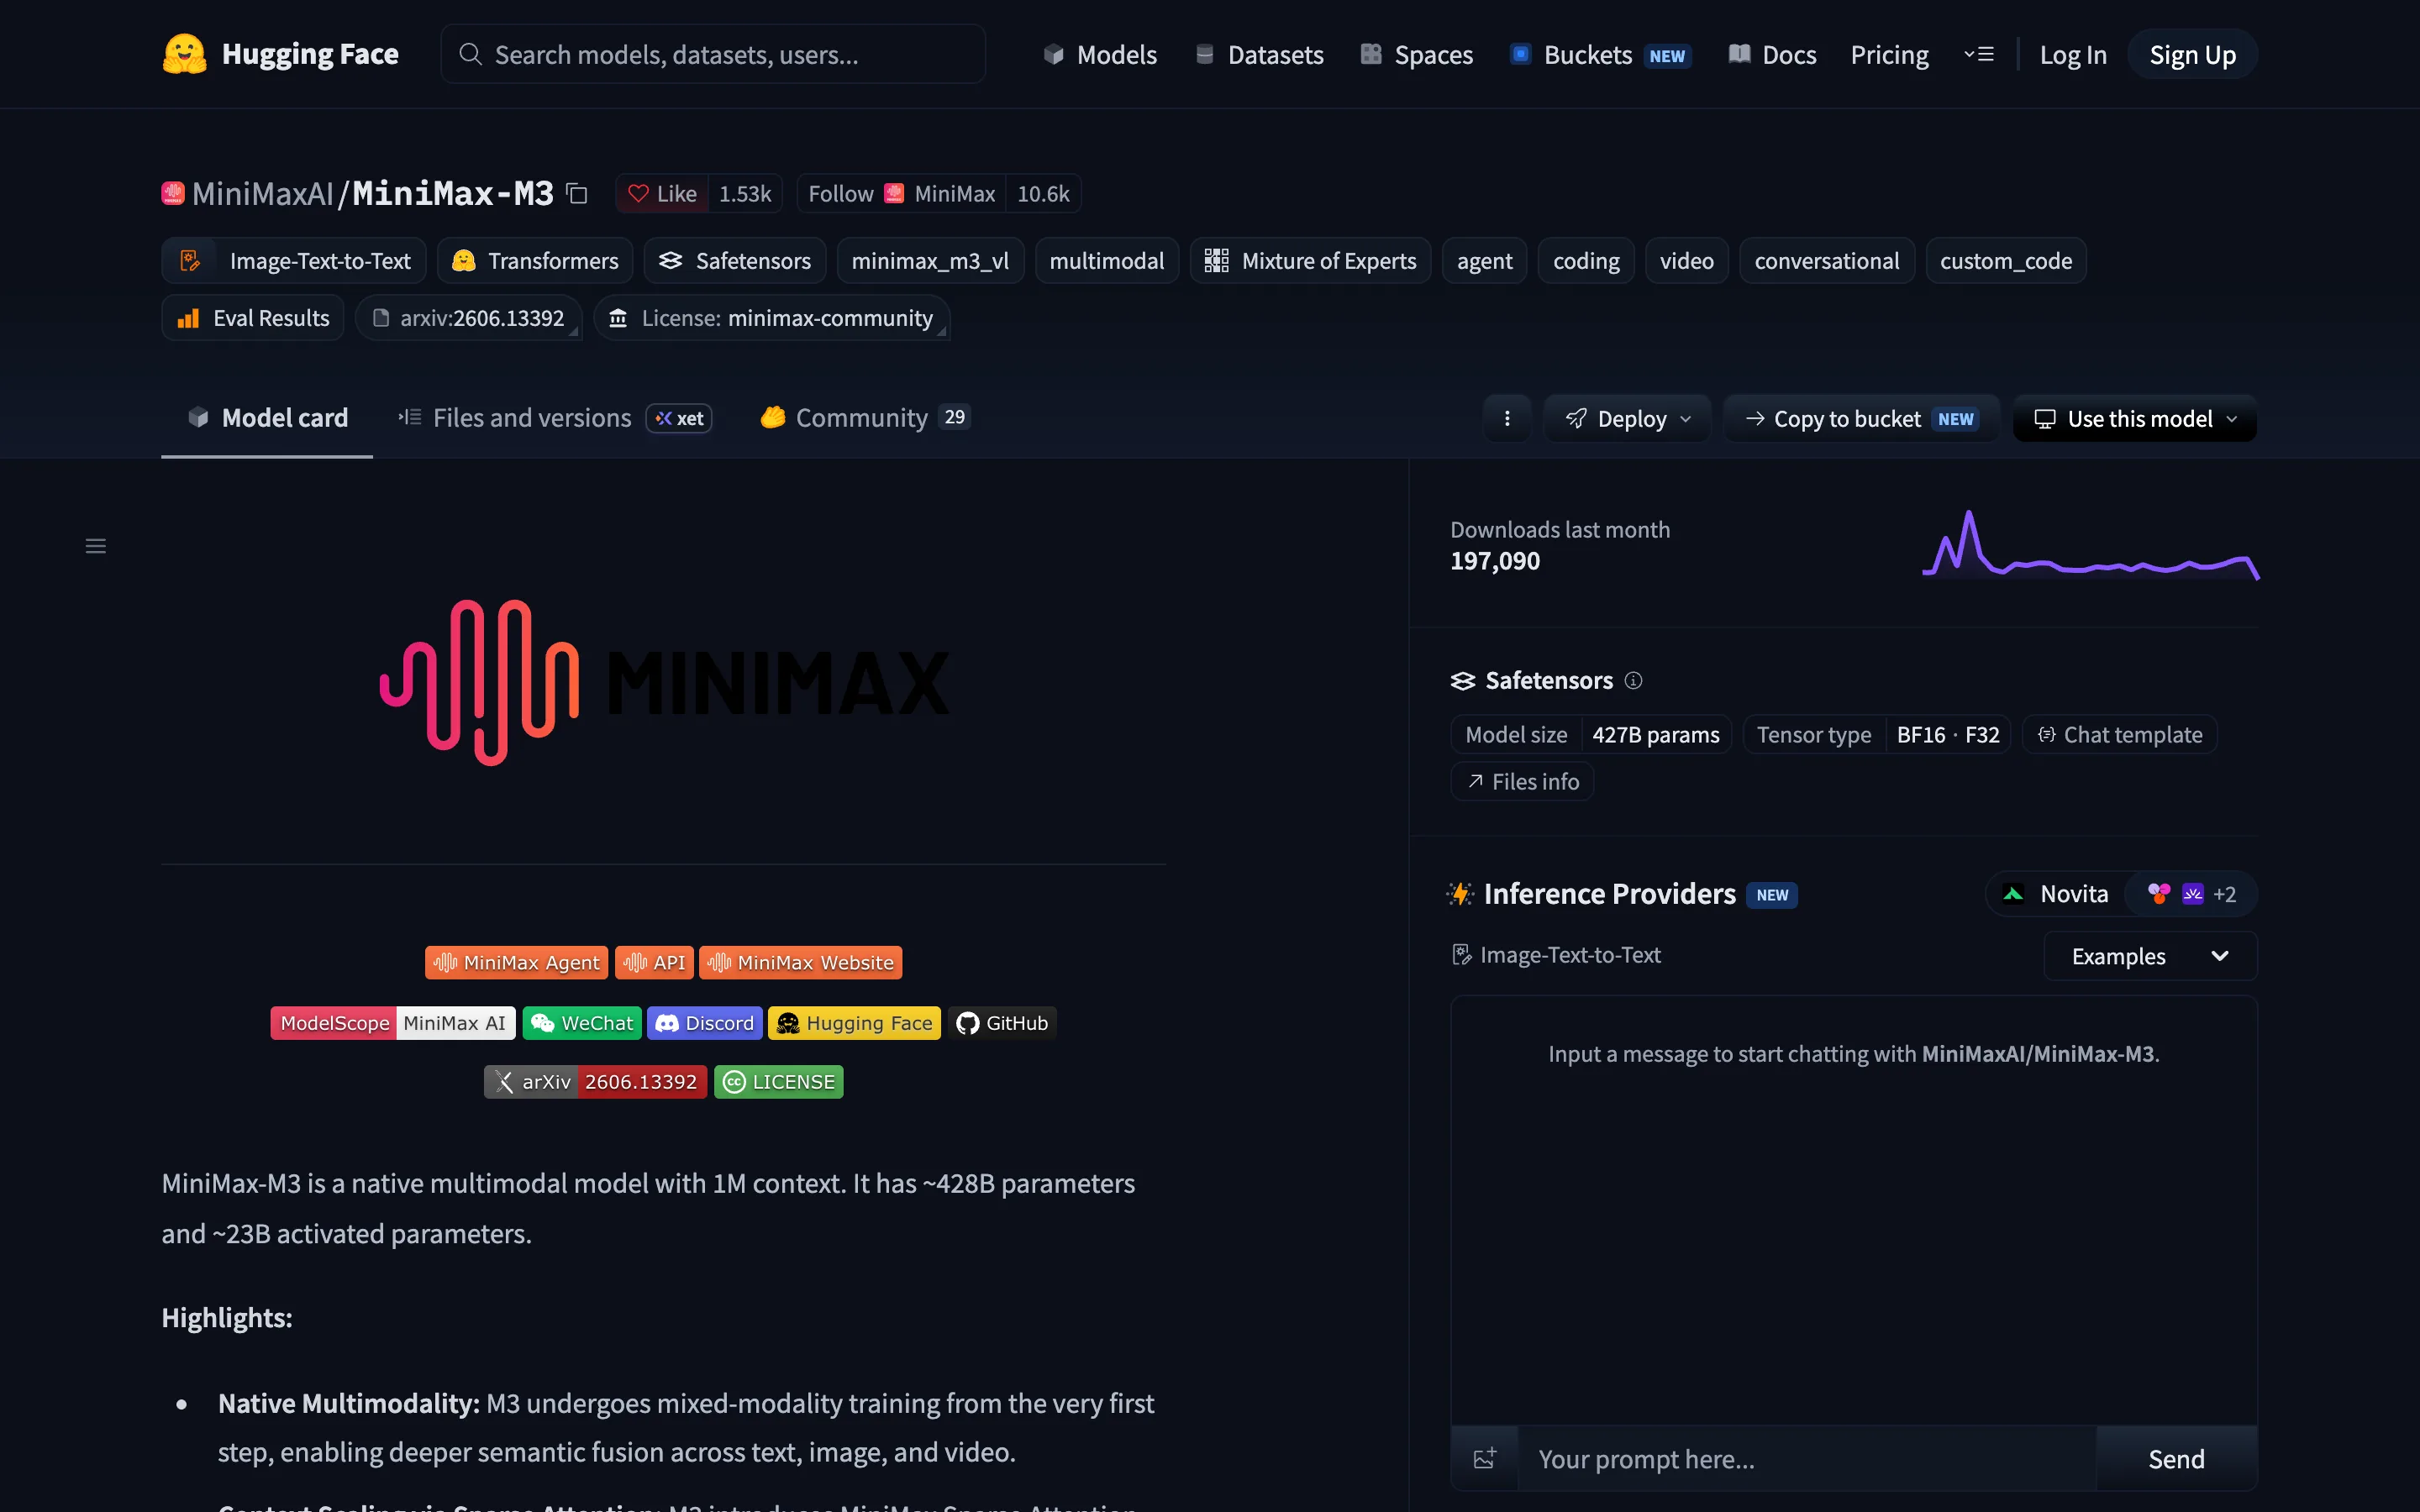
MiniMax-M3 is a native multimodal MoE with roughly 427B total and 23B activated parameters and a 1M-token context, at 176,425 Hugging Face downloads on the day the screenshot was taken (November 5, 2026). MiniMax-M3.1-Flash, created October 17, 2026, is also cloud-only on Ollama.
Inkling
Inkling has 1,862,861 Hugging Face downloads in 30 days and no Ollama tag. There is a community path to running it: Unsloth publishes GGUF quantizations; its unsloth/inkling-GGUF repository had 241,361 downloads in the same window.
Kimi K3
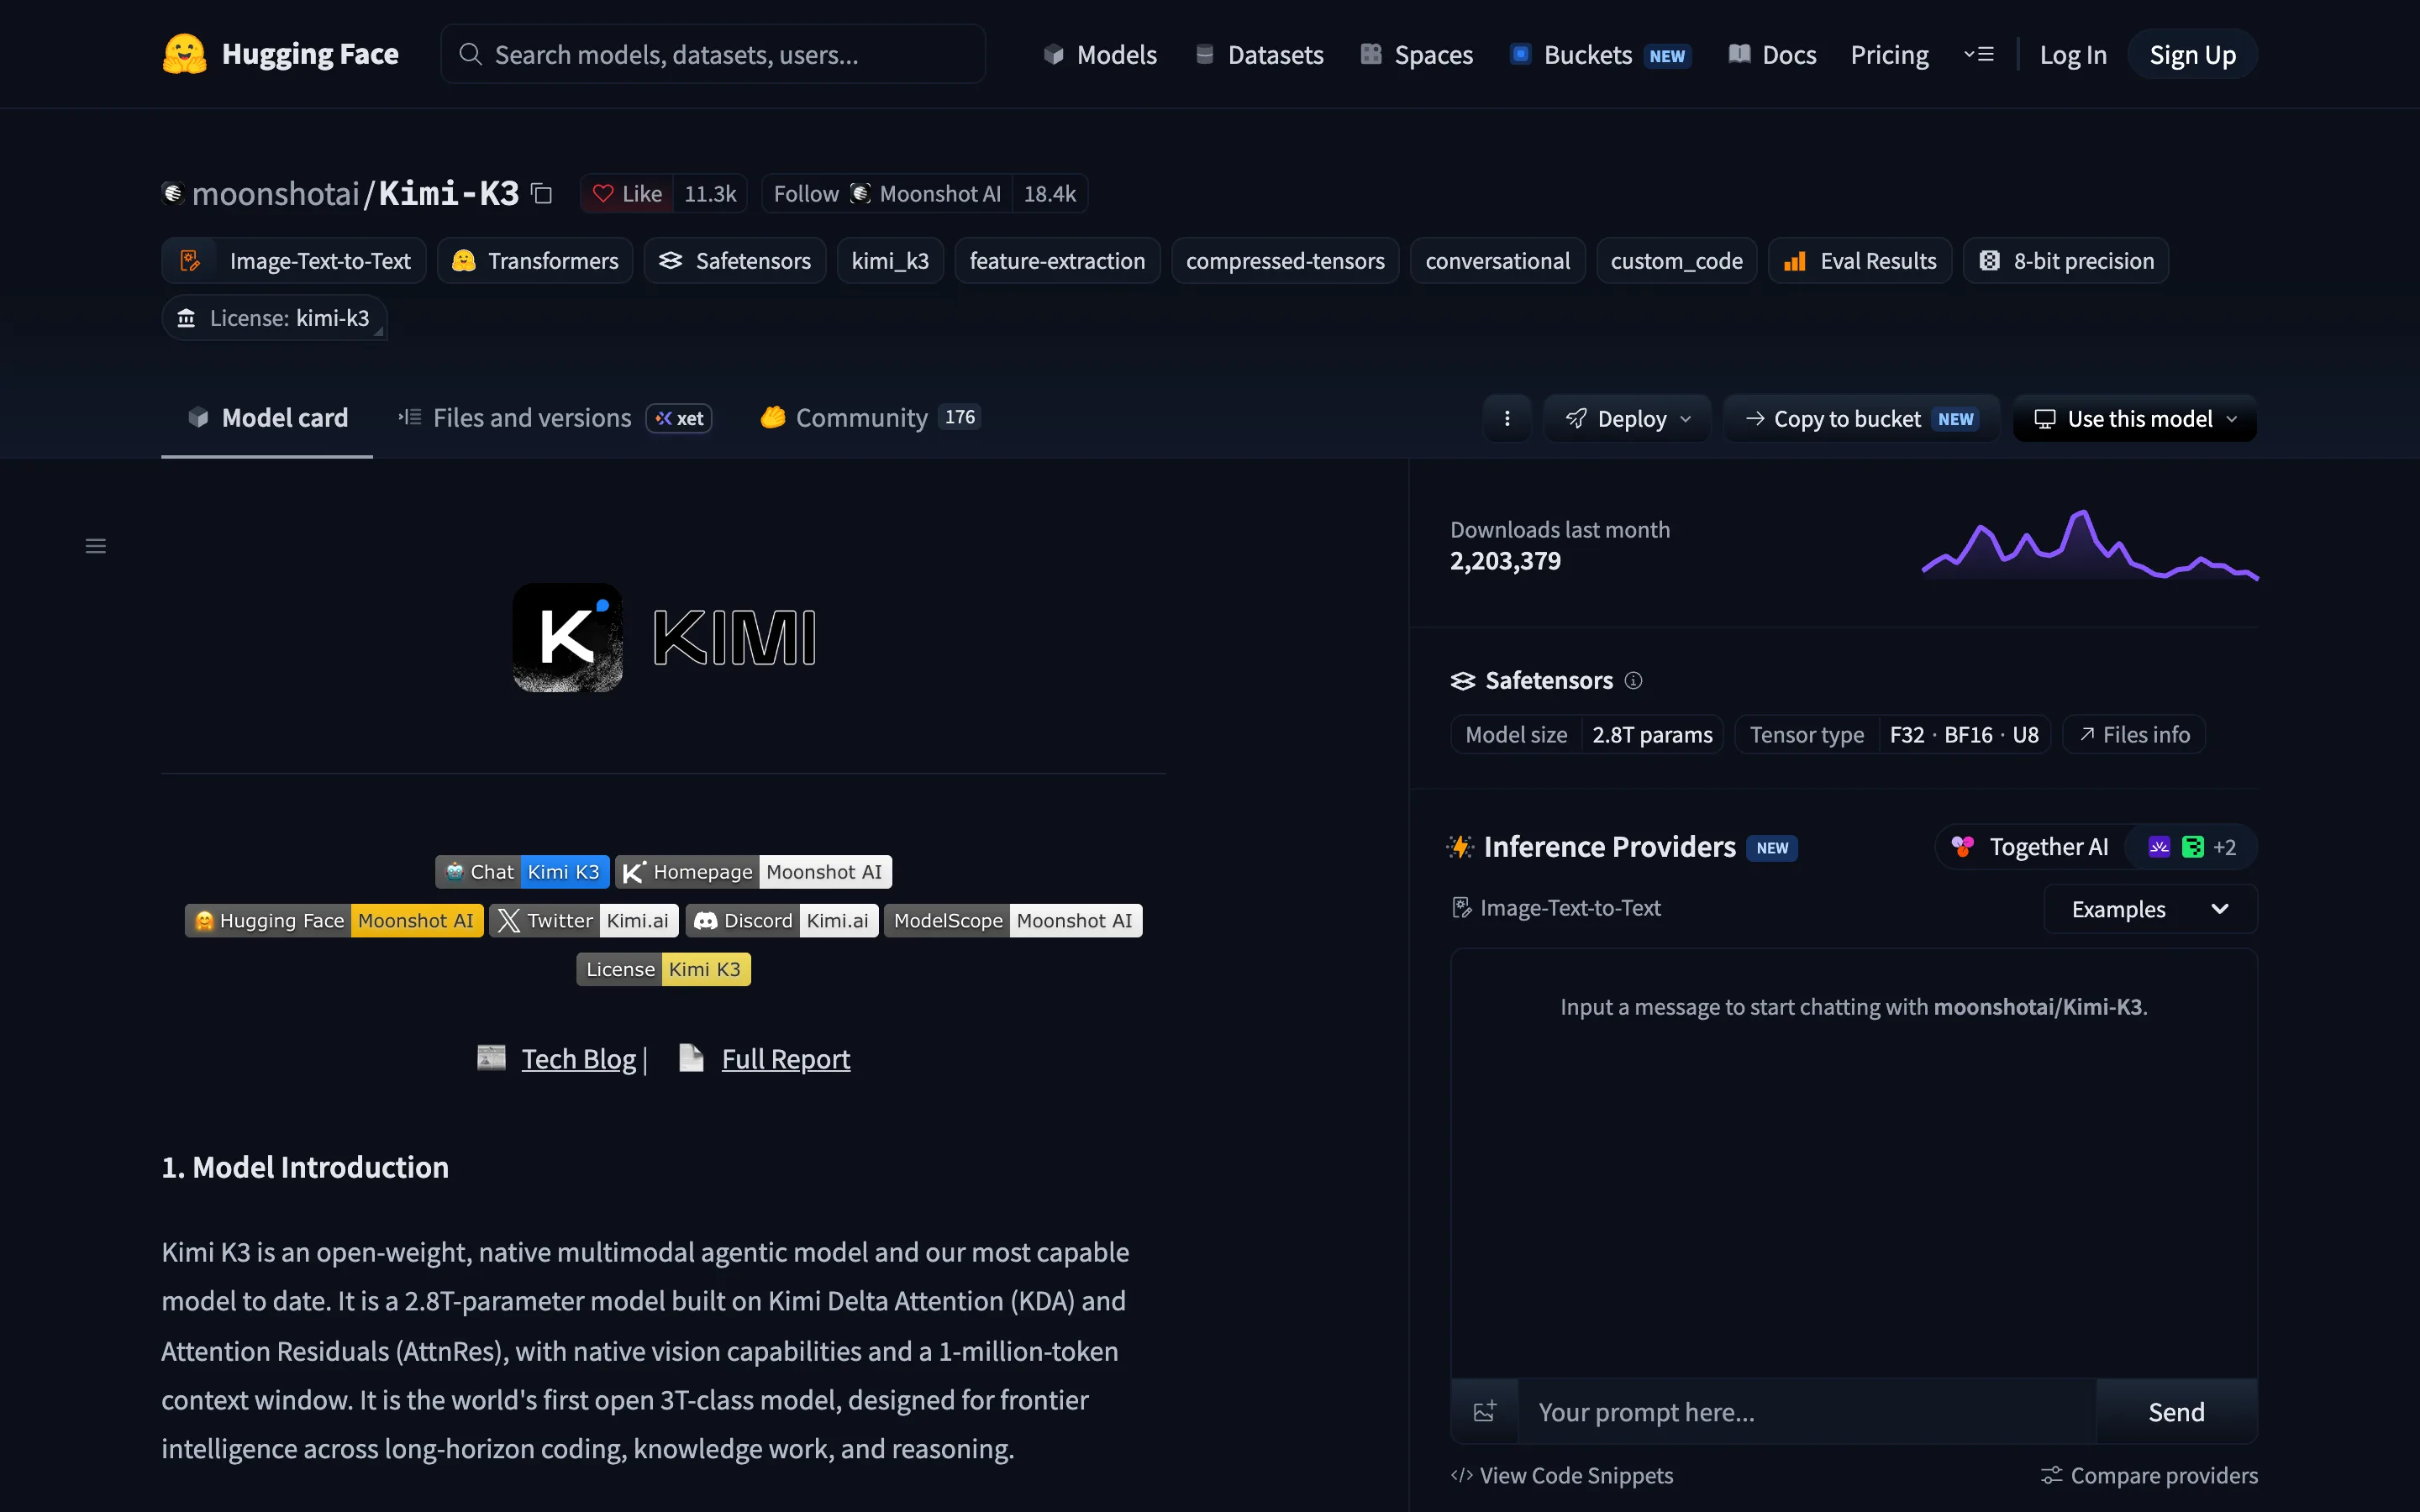
Kimi K3 is an open-weight, native multimodal agentic model with 2.8T parameters and a 1M-token context, at 768,725 Hugging Face downloads in the 30 days to November 5, 2026. Ollama lists it cloud-only, and so is Kimi K3.1 Pro, which appeared on Hugging Face on November 2, 2026.
Where's Llama?
The newest Llama repositories under meta-llama on Hugging Face are Llama 4, from April 2025. Meta announced Muse Spark on April 8, 2026, and its Muse Spark Open model (816B total, 42B active) appeared on Hugging Face on September 15, 2026. Ollama lists it cloud-only.
Older Tags That Still Pull
phi4:14b is 9.1 GB and mistral-small3.2:24b is 15 GB on Ollama. The picks above cover the same sizes with newer weights.
Production Hardware Realities: Math You Cannot Ignore
VRAM is the physical chokepoint. At 4 bits a parameter is half a byte, so weights alone take about 0.5 GB per billion parameters; the KV cache and runtime push the rule of thumb to 0.6 to 0.7 GB. The download sizes above are the honest check on any claim.
- Laptop, 16 GB: MiMo-V2.6 (6.6 GB) or Gemma 4 12B (7.7-8.0 GB). An 8 GB card holds the first with little room for context and cannot hold the second once runtime overhead is counted.
- Consumer GPU, 24 GB: Gemma 4 26B (16-19 GB) or Qwen3.8 27B (18 GB). Flint (22.9 GB) loads but leaves almost no cache room.
- Beyond a desk: using the weights-only figure, GLM-5.3 (753B) is about 376 GB, MiniMax-M3 (427B) about 214 GB and Kimi K3 (2.8T) about 1.4 TB, before any KV cache.
Conclusion
The useful question in 2026 is no longer "is it open weight" but "is there a file I can download". Five of the ten models here have a real local tag, and all but Flint fit a single 24 GB GPU with room to spare; the rest are open in license and data-center-scale in practice.
Pick by download size, not parameter count:
- Laptop, 16 GB: MiMo-V2.6 (6.6 GB) or Gemma 4 12B (7.7-8.0 GB)
- Consumer GPU, 24 GB: Gemma 4 26B (16-19 GB) or Qwen3.8 27B (18 GB)
- Coding agent, 32 GB or more: Flint (22.9 GB)
- Hosted open models: Kimi K3, GLM-5.3, MiniMax-M3 and DeepSeek-V4 as
cloudtags
Pull it with Ollama, point your existing OpenAI-compatible code at localhost, and the token meter stops running.
Related DevToolLab Tools
- LLM VRAM Calculator - check whether a model and quantization fit your GPU before you download a multi-gigabyte file.
- GGUF Viewer - read the architecture and quantization of a downloaded GGUF file without loading the model.
- LLM Token Cost Calculator - price the cloud usage you are replacing, so the hardware spend has a payback number attached.
- Port Checker - confirm Ollama on 11434 or LocalAI on 8080 is actually listening before you debug a "connection refused" that is really a stopped daemon.
Related Guides
- Local LLM VRAM Requirements - the sizing math behind the download figures above, per model and quantization.
- How to Run an LLM Locally on Mac or PC - a step-by-step Ollama install with real output.
- Qwen3.8 27B VRAM Requirements, Measured - what the 18 GB pull actually uses at different context lengths.
- Local LLM Hardware: GPU vs Mac in 2026 - which machine to buy for the 24 GB tier.