Found 1 article tagged with "evaluate large language model output"
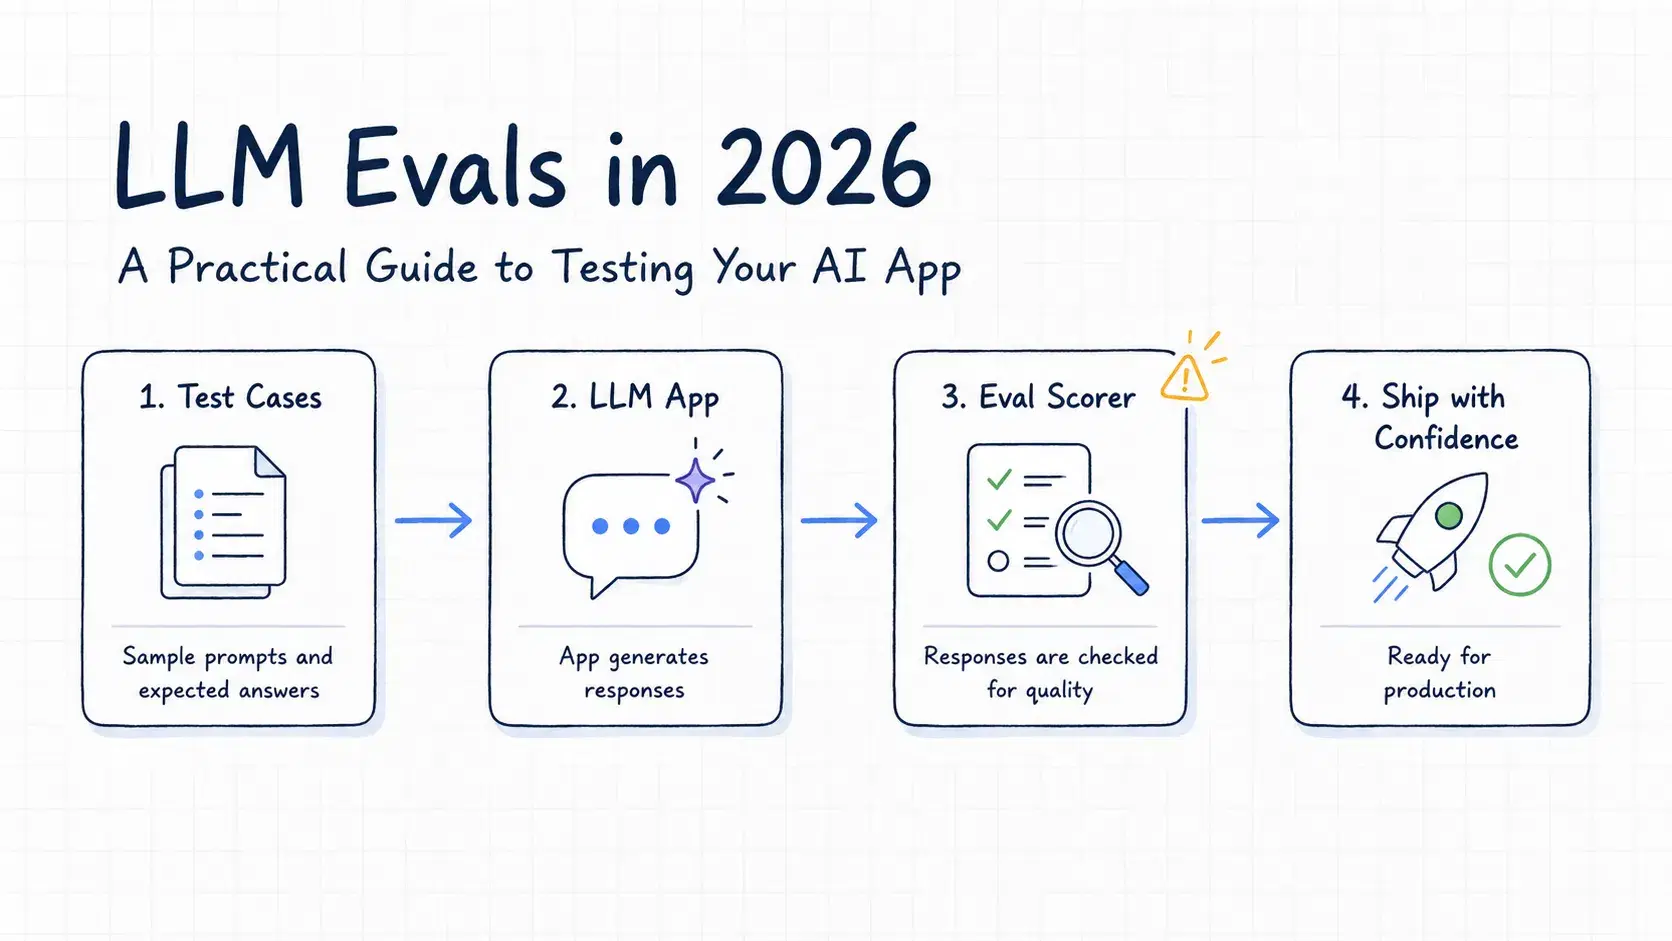
LLM apps break silently - a changed prompt, a model update, and your outputs drift without an assertion firing. This guide covers the three eval types, a working Python harness, LLM-as-judge, and CI integration.